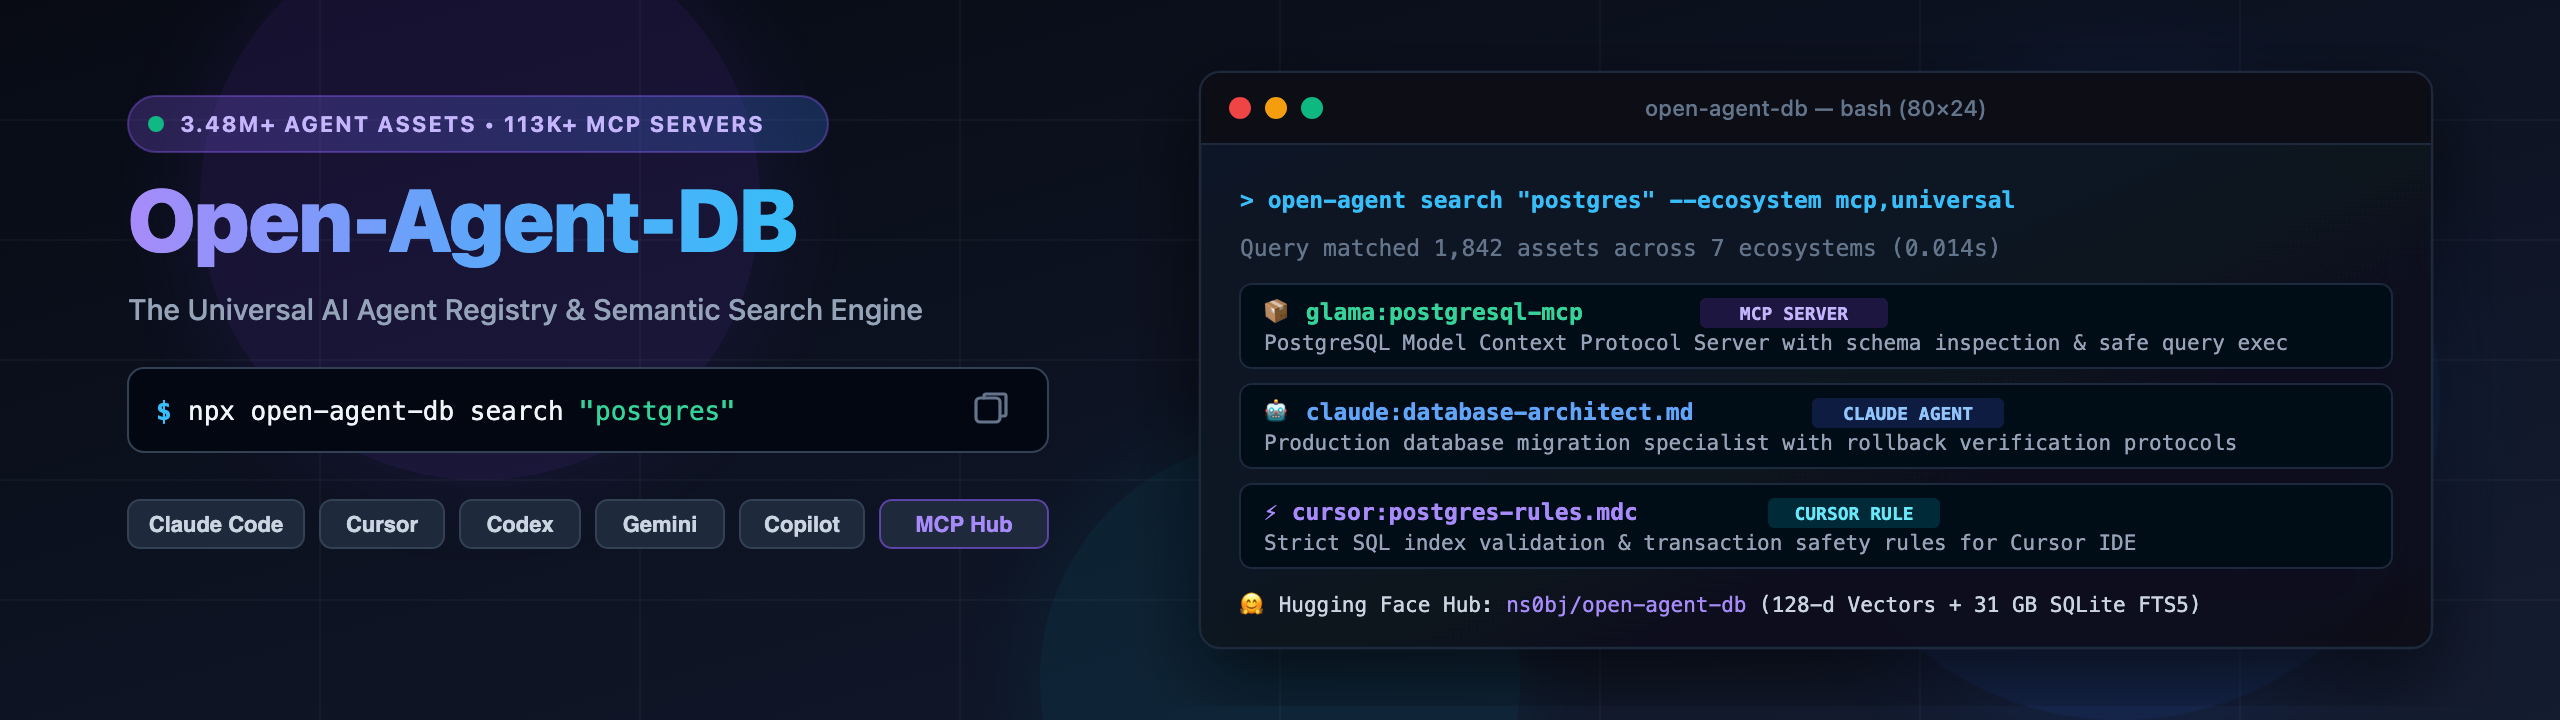
Open-Agent-DB
The Universal Open Database and Semantic Vector Search Engine for AI Agent Skills, MCP Servers, Project Directives, and Rules.
Open-Agent-DB aggregates and indexes over 3,480,000+ Agent Assets and 113,000+ Model Context Protocol (MCP) Servers across every major AI coding assistant ecosystem, including Anthropic Claude Code, Cursor, OpenAI Codex, Google Gemini, GitHub Copilot, and OpenCode.
Sub-second Full-Text Search
SQLite FTS5 query engine provides instant search across 3.48M+ records and source files.
Semantic Vector Engine
Pre-computed 128-dimensional dense vector embeddings for natural language similarity search.
Unified Hugging Face Hub
Dual-engine hosting: both Vector Parquet and 30+ GB SQL archives available under one dataset.
1-Click Installer
Direct export and install to ~/.claude/skills/, Cursor rules, and Claude Desktop configs.
⚡ Quick Start (Zero-Install)
You can run Open-Agent-DB immediately using Node.js without downloading or configuring anything:
# Search across all indexed assets
npx open-agent-db search "postgres"

# Inspect MCP server details & install command
npx open-agent-db info "Prisma Postgres"

# Generate Claude Desktop MCP JSON config snippet
npx open-agent-db install "Prisma Postgres"
📦 Global Installation
Via NPM (Node.js ecosystem)
npm install -g open-agent-db
open-agent search "docker"
Via Pip (Python & AI ecosystem)
pip install open-agent-db
open-agent search "react"
🧠 Semantic Vector Search
Open-Agent-DB includes a native Vector Search Engine that allows natural language semantic queries over skills, tools, and directives:
# Natural language semantic query
python3 vector_search.py "automate database schema migrations with safety checks"

# Search for specific tools with top-K limit
python3 vector_search.py "ios swift metal shader visual effects" --top-k 5

# Rebuild local vector embeddings index from SQLite
python3 vector_search.py --build --limit 50000
Python Pure Vector Search (NumPy / Cosine Distance)
You can also load the vector embeddings directly in Python and run lightning-fast matrix similarity calculations without FAISS:
from datasets import load_dataset
import numpy as np

# 1. Load pre-computed vector dataset from Hugging Face
dataset = load_dataset("ns0bj/open-agent-db", data_files="open_agent_db_vectors.parquet", split="train")

# 2. Extract dense float32 embedding matrix (Shape: N x 128)
embeddings = np.vstack(dataset["embedding"])

def search_by_embedding(query_vector, top_k=5):
    # Normalized cosine similarity
    query_norm = query_vector / (np.linalg.norm(query_vector) + 1e-9)
    scores = np.dot(embeddings, query_norm)
    top_indices = np.argsort(scores)[::-1][:top_k]
    return [(scores[idx], dataset[int(idx)]["name"], dataset[int(idx)]["ecosystem"]) for idx in top_indices]
🗄️ Universal SQL Database
The complete offline SQLite database contains 3.48M+ assets with full text search (FTS5), relational schema indices, and compressed raw source code BLOB files. Highly compressed down to ~12.5 GB with Zstandard (expands to a pristine 31 GB SQLite database in ~10 seconds).
# 1. Download compressed archive via huggingface-cli
hf download ns0bj/open-agent-db open_agent_db_sql.sqlite.zst --repo-type dataset --local-dir ./data

# 2. Decompress to pristine 31 GB SQLite database (takes ~10 seconds on macOS / Linux)
unzstd ./data/open_agent_db_sql.sqlite.zst -o ./data/open_agent_db.sqlite

# 3. Quick verification
sqlite3 ./data/open_agent_db.sqlite "SELECT count(*) AS total_assets FROM assets;"
📋 Database Schema Reference
The database is organized into two primary tables connected via foreign keys, plus an automated sync ledger:
| Table | Key Columns | Description |
|---|---|---|
assets |
id (PK), ecosystem, asset_kind, name, description, author, stars, forks, github_url, raw_url, source_path, canonical_key, crawled_at, parsed_metadata_json |
Core catalog table holding metadata, star counts, author profiles, and ecosystem classifications across all 3.48M+ assets. |
files |
id (PK), asset_id (FK), path, size, content (BLOB), is_compressed |
Source code repository holding actual file contents (e.g. SKILL.md, mcp.json, .cursorrules, system prompts) stored as raw or zlib-compressed bytes. |
sync_history |
id, sync_date, total_assets, mcp_servers, vector_records, duration_seconds, status |
Automated monthly release ledger tracking new asset counts, sync timings, and data freshness. |
💡 Practical SQL Query Playbook
You can execute powerful queries against the database using any standard SQLite client, Python, or DuckDB:
1. Discover Top MCP Servers by Stars or Keyword
SELECT name, author, stars, source_path,
       json_extract(parsed_metadata_json, '$.install_command') AS install_cmd
FROM assets
WHERE ecosystem = 'mcp' AND (name LIKE '%postgres%' OR description LIKE '%database%')
ORDER BY stars DESC
LIMIT 10;
2. Extract Actual Source Code or Configuration from BLOBs (Python)
import sqlite3
import zlib

conn = sqlite3.connect("data/open_agent_db.sqlite")
cursor = conn.cursor()

# Retrieve the full source code or config for any skill / MCP server
cursor.execute("""
    SELECT a.name, a.ecosystem, f.path, f.content, f.is_compressed
    FROM assets a
    JOIN files f ON a.id = f.asset_id
    WHERE a.id = 'glama:modelcontextprotocol/postgresql'
""")
row = cursor.fetchone()
if row:
    name, eco, path, blob, is_comp = row
    content_text = zlib.decompress(blob).decode('utf-8') if is_comp else blob.decode('utf-8')
    print(f"Asset: {name} ({eco})\nPath: {path}\n---\n{content_text[:400]}...")
3. Ecosystem Asset Distribution & Statistics
SELECT ecosystem, asset_kind, count(*) AS total_count, max(stars) AS max_stars
FROM assets
GROUP BY ecosystem, asset_kind
ORDER BY total_count DESC;
4. Direct Cloud Analytics via DuckDB (Zero 30GB Download Required!)
Using DuckDB's HTTPFS extension, you can query Parquet metadata directly from Hugging Face without storing gigabytes locally:
-- Run directly in DuckDB CLI or Python
INSTALL httpfs; LOAD httpfs;

SELECT ecosystem, count(*) AS total_assets, round(avg(stars), 1) AS avg_stars
FROM 'https://huggingface.co/datasets/ns0bj/open-agent-db/resolve/main/open_agent_db_vectors.parquet'
GROUP BY ecosystem
ORDER BY total_assets DESC;
🤗 Hugging Face Hub Integration
Open-Agent-DB provides a unified Hub on Hugging Face Datasets: ns0bj/open-agent-db.
Loading Vector Embeddings in Python (2 Lines)
from datasets import load_dataset

# Load vector embeddings directly from Hugging Face
dataset = load_dataset("ns0bj/open-agent-db", data_files="open_agent_db_vectors.parquet", split="train")

# Add native FAISS index for sub-millisecond similarity search
dataset.add_faiss_index(column="embedding")
scores, samples = dataset.get_nearest_examples("embedding", query_vector, k=5)
🧩 Supported Ecosystems
| Ecosystem | Target Files | Asset Kind | Description |
|---|---|---|---|
| MCP | mcp.json, APIs |
mcp_server |
Official Anthropic Registry, Glama, Smithery, Awesome MCP |
| Claude Code | CLAUDE.md, .claude/agents/*.md |
project_rules, agent_brief |
Anthropic Claude Code CLI configurations & personas |
| Cursor | .cursorrules, *.mdc |
project_rules, trigger_rule |
Cursor IDE rules and trigger-based .mdc specifications |
| OpenAI Codex | .codex/agents/*.md |
agent_brief, workflow |
OpenAI Codex CLI agents and plugin specifications |
| Google Gemini | GEMINI.md, skills |
project_rules, skill |
Google Antigravity & Gemini CLI directives |
| GitHub Copilot | copilot-instructions.md |
project_rules |
GitHub Copilot Workspace custom guidelines |
| Universal | SKILL.md, AGENTS.md |
skill, project_rules |
Cross-platform open agent rules and tool skills |
🔌 MCP Server Registry (113k+)
Open-Agent-DB unifies the world's leading Model Context Protocol repositories into a single index:
- Glama MCP Registry: 86,800+ indexed servers with category classification.
- Official Anthropic Registry: 15,600+ verified MCP servers.
- Smithery.ai: 10,000+ servers with one-click install commands.
- Awesome MCP: 3,800+ curated developer utilities.
🤖 AI Agent Integration
Equip your coding assistants (Claude Code, Cursor, Codex, Gemini) with Open-Agent-DB capabilities by referencing AGENTS.md or installing the global agent directive:
# Open-Agent-DB Integration Rule
When searching for existing skills, MCP servers, or project rules:
1. Run: npx open-agent-db search ""
2. Inspect server config: npx open-agent-db info ""
3. Apply canonical SKILL.md and AGENTS.md conventions from open-agent-db.
💻 CLI Command Reference
| Command | Description | Example |
|---|---|---|
search |
Search skills & MCP servers by keyword or ecosystem | open-agent search "prisma" --ecosystem mcp |
info |
Display detailed metadata, parameters, and install code | open-agent info "Brave Search" |
install |
Output ready-to-use JSON for Claude Desktop / Cursor | open-agent install "gmail" |
stats |
Show breakdown of indexed ecosystems & asset counts | open-agent stats |
🔄 Aylık Otomatik Senkronizasyon
Open-Agent-DB uses an automated incremental pipeline scheduled via macOS launchd on the 1st of every month at 03:00 AM:
- Delta Harvester: Fetches newly published MCP servers and GitHub assets.
- Vector Re-indexing: Generates dense embeddings for new records.
- Online Snapshot & zstd: Creates a pristine SQLite backup without interrupting active writers.
- Hugging Face Push: Updates the unified dataset at
ns0bj/open-agent-db.